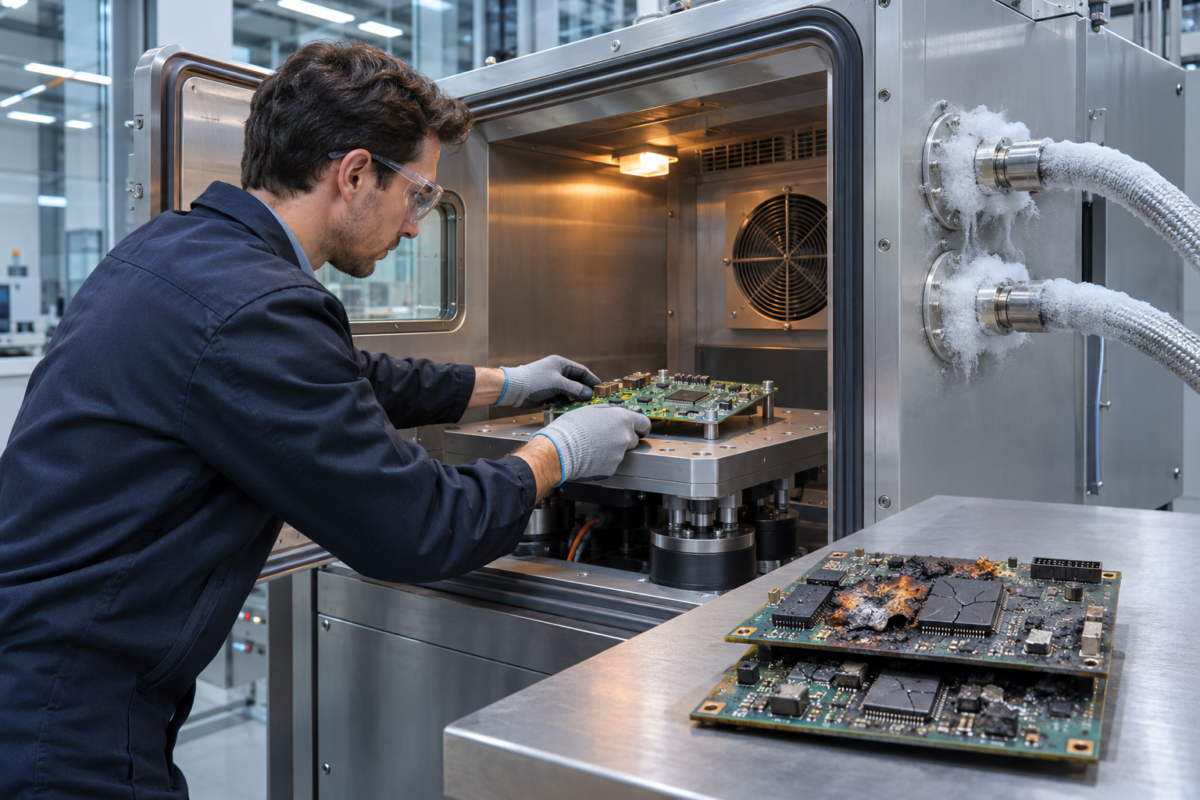
Highly Accelerated Life Testing is not a qualification test. The most common mistake I see across two decades in automotive and aerospace quality is engineers writing HALT results into a pass/fail matrix as if the chamber were a certification body. HALT is a discovery tool: its purpose is to find the operating and destruct limits of a design — the point where the product stops working, and the point where it stops working permanently — before anyone has committed to a production release.
The philosophy is straightforward. A product that survives to a destruct limit far beyond its intended environment has margin; a product that falls over just past its specified envelope does not, and the field will eventually find the same weak joint you found in the chamber, with warranty claims attached. You are trading a handful of deliberately destroyed prototypes for the avoidance of uncontrolled field failures. In my experience that trade is almost always worth making, provided you test early enough to act on what you learn.
HALT applies combined stresses — rapid thermal cycling, multi-axis random vibration, often power cycling and supply-voltage margining — at levels well beyond the datasheet. The combination matters: thermal transitions together with vibration will find solder joint fatigue, connector fretting, bracket resonances and cracked potting compounds that neither stress finds alone at lower amplitudes.
Stress stepping: how the profile is built
A HALT profile is built in steps, not ramps held at qualification levels. Start with a step-stress cold and hot search: hold each temperature long enough for the internal mass — not just the chamber air — to reach equilibrium, then step by five or ten degrees, dwell, functionally test, and continue until the product fails functionally or the chamber limit is reached. Apply the same approach to vibration, stepped in increments of roughly ten gravities of broadband random energy, with full functional test at every step.
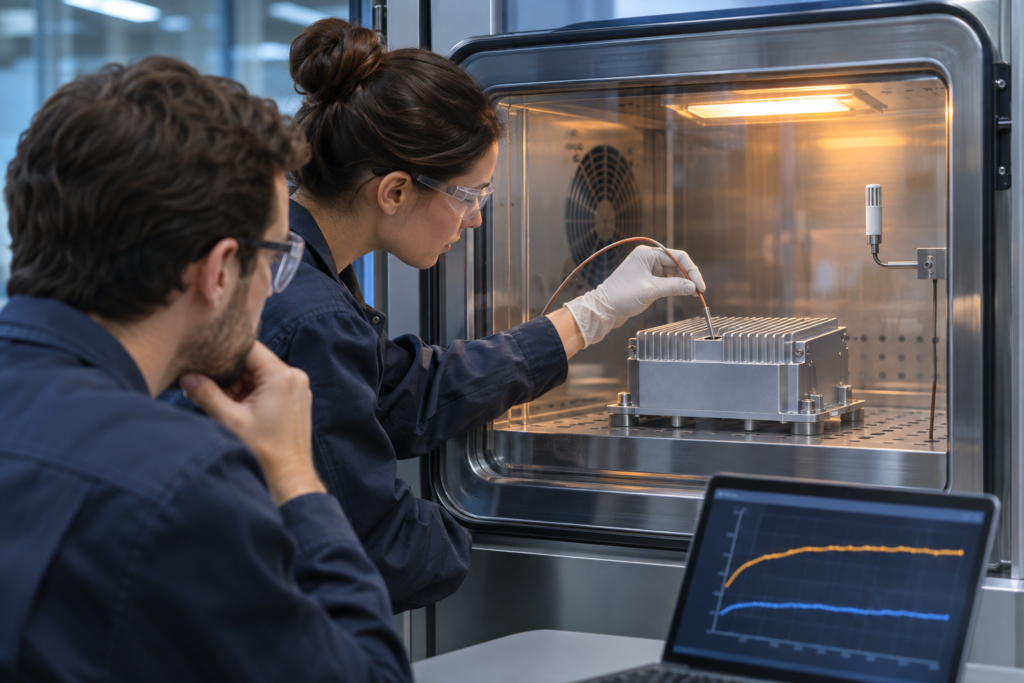
Dwell time is where teams go wrong. Chamber air temperature stabilises quickly; a power module with a large heatsink or a potted electronics assembly does not. Monitor thermocouples attached to internal components rather than trusting the chamber readout, or you will step past a real limit believing you have dwelt properly. I have seen limits underestimated by a considerable margin purely because the product never caught up with the chamber between steps.
Once individual stress limits are known, combine them. The classic combined profile runs thermal transitions between the discovered operational limits while vibration is stepped upward, because that is where the true destruct limit usually hides. High ramp rates — a good HALT chamber achieves tens of degrees per minute — drive differential expansion that vibration then converts into cracks, lifted leads and fractured via joints.
Operational limits, destruct limits, and what each tells you
Two numbers come out of the step search for each stress. The operational limit is the point beyond which the product fails functionally but recovers when the stress is removed; the destruct limit is the point beyond which it fails permanently. A low operational limit with a high destruct limit suggests soft failure modes — a regulator dropping out, a crystal stopping, firmware hanging — which are often fixable in software or circuit design. A destruct limit close to the operational limit suggests fragile hardware: a cracked component, a delaminating board, a sheared mounting tab.
Record the failure mode at every halt point, not just the stress level. A product that stops working at minus forty but recovers, traced to a display that will not refresh, is a different engineering problem from one that stops at minus forty because a solder joint fractured. The stress level without the physical mechanism is nearly useless information. Teardown and failure analysis of every destruct unit is non-negotiable; that is where the design insight lives.
The margin judgement comes next. Compare destruct limits against the product's expected life environment — the automotive thermal spec, the vibration spectrum of the intended installation. If the vibration destruct limit sits comfortably above the qualification level for the application, you have demonstrated robustness. If it barely clears it, HALT has done precisely its job: the weak point failed in your chamber, on your schedule, with your engineers watching.
HASS: screening production, not discovering failures
Highly Accelerated Stress Screening is the production-line sibling, and the distinction from HALT must be kept sharp. HALT finds design limits; HASS removes manufacturing defects from shippable product using a profile derived from those limits. A typical profile is a precipitation regime — stresses near or slightly beyond the operational limits to turn latent defects into detectable faults — followed by a detection regime at safely within-limits levels where full functional test proves the product still works.
The targets are latent defects: cold solder joints, contaminated connectors, missing adhesive, handling damage, marginal wire bonds. None of these will fail at end-of-line test at room temperature. Some percentage will fail in the field after months of thermal cycling and road vibration. HASS compresses that timeline into hours in a chamber, so the defect escapes to a rework station rather than to a customer.
Screening strength must be proven before the profile is released to production. The established method is to inject known-bad units — parts deliberately seeded with representative defects — and demonstrate the profile catches them, while simultaneously running good units through repeated cycles to prove the screen does not consume significant life of healthy product. That safety proof is the step most often skipped by people under schedule pressure. A screen that weakens good product is worse than no screen at all.
From discovery to controlled screening
- 01HALT on designStep-stress to operational and destruct limits on early hand-built units
- 02Fix and re-HALTAction destruct-limit findings, then re-map limits on the revised design
- 03Derive HASS profileSet precipitation and detection regimes from the proven limits
- 04Prove the screenCatch seeded defects; show good units survive repeated cycles
- 05Screen and feed backTrack fallout as manufacturing intelligence and fix upstream causes
Keeping discovery and screening apart
The organisations that struggle with accelerated stress are the ones that blur discovery and screening. A HALT chamber loaded with production units just to check is neither a discovery test nor a validated screen — it produces failures nobody has budgeted time to analyse, and the data goes nowhere. Run discovery during design, run screens during production, and let the screen profile be formally derived from the HALT results with a documented safety proof.
If you are screening but never fixing the upstream causes, you have built an expensive sorting operation and called it quality.
There is also a temptation, once HASS is running, to treat fallout as background noise. Screening fallout must be tracked, analysed and fed back: a rising fallout rate is a process drifting out of control, whether the cause is a wave solder bath, a wearing crimp tool, or a component supplier change. The screen exists to protect the customer while you eliminate the defects; it is a bridge, not a destination.
Screens also need periodic revalidation. When the design changes — a new component lot, a layout revision, a substituted connector — the old profile may no longer stress the new weak points. I insist on a light re-HALT at every significant design revision, because a screen tuned to the previous revision's limits can silently lose effectiveness on the current one.
Failure modes worth expecting
Certain failure modes appear so reliably in HALT that you can nearly predict them before the chamber door closes. Solder joint fatigue at large, rigid components — inductors, transformers, large ceramic capacitors — is the classic, driven by coefficient-of-expansion mismatch during rapid thermal transitions. Connector contact fretting under vibration is another, particularly where housings allow relative motion between mating halves. Bolted and staked mechanical joints loosen under multi-axis vibration far faster than under the single-axis sweep of a conventional qualification test.
Board-level problems show up as well: via cracking on heavy copper planes, delamination where moisture has been trapped, and trace cracking at board-mounting points where the standoff imposes bending. Power supplies reveal their soft limits — protection circuits tripping, controllers latching — which frequently turn out to be firmware behaviour rather than hardware fragility. Each of these findings is a design input, not a rejection; the value is in finding them while the drawing can still be changed.
Instrument the units properly during test. Monitor supply rails, critical signals and functional performance continuously through the stress steps rather than testing only at dwell, because intermittent faults that appear during transitions but vanish at steady state are exactly the field-failure signature you are hunting. A fault logged with its stress level and time stamp is worth ten faults noticed afterwards during bench debugging.
Where the failures should happen
Failure found in HALT
- Occurs before design freeze
- Root cause analysed with engineers present
- Fix is a drawing change: stack-up, bracket, component
- Costs a prototype unit on a known date
Failure found in the field
- Occurs after production release
- Root cause traced through warranty returns
- Fix is a change order, stock rework, containment
- Costs claims, reputation and schedule you did not choose
Making the business case and getting the timing right
The objection I hear most often is cost: chambers are expensive, prototypes are scarce, and destroying units feels wasteful. My counter is always timing. HALT performed on early hand-built units, when the design is still fluid, changes outcomes cheaply — a stack-up revised, a bracket thickened, a component swapped. HALT performed on production-intent tooling after the design freeze produces findings nobody can afford to action, and the report becomes a museum piece.
Prototype scarcity is real, particularly in low-volume aerospace work, but HALT does not need many units. Two or three well-instrumented units per major design revision is often enough to map limits, provided you do proper failure analysis on each halt. What it genuinely cannot tolerate is delay: every week the first HALT units slip later in the programme, the cost of acting on the findings rises.
Done properly, the sequence is fixed. HALT during design, fix the destruct-limit findings, re-HALT on the revision, derive the HASS profile, prove it safe on good units and effective on seeded units, then screen production and treat fallout as manufacturing intelligence. Break the parts you can afford to break, on the day you choose, and the field will have far fewer opportunities to break them for you.