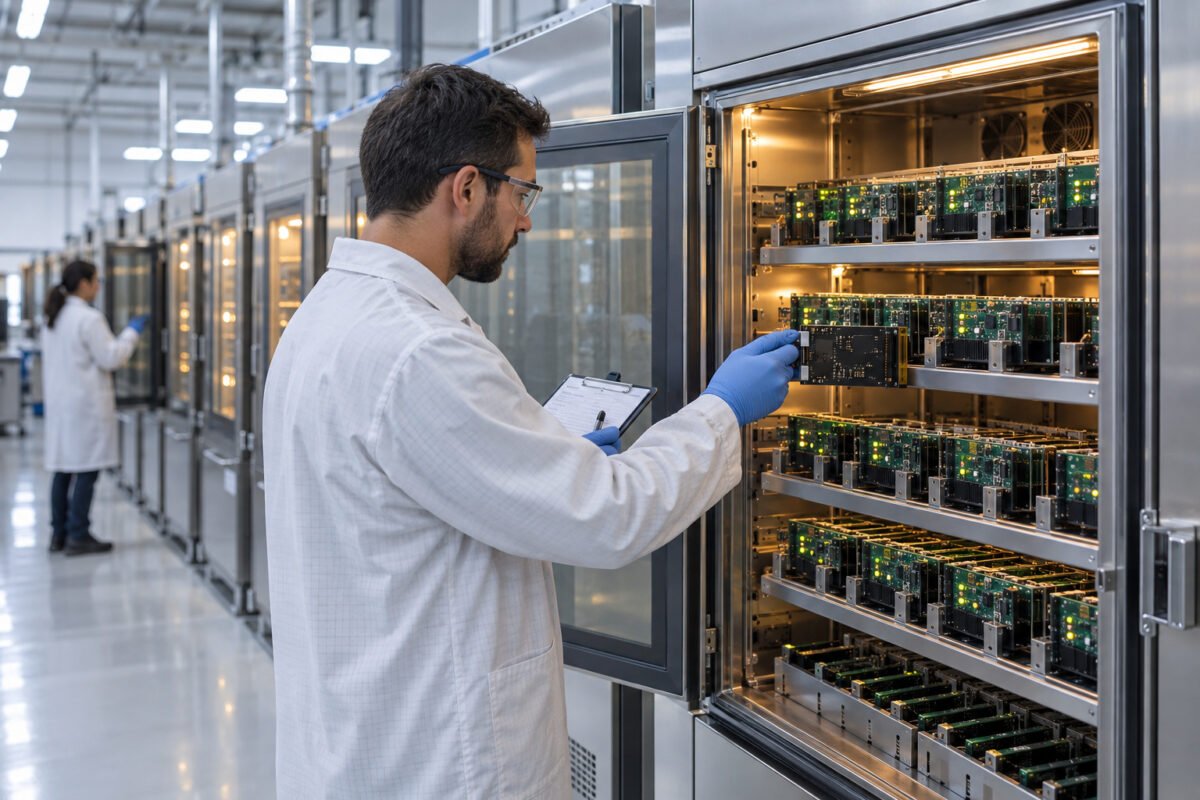
Every hour of burn-in consumes useful life from every unit that passes through it. That is the arithmetic at the centre of any screening strategy. You pay three times: once in chamber capital and energy, once in throughput time lost at the end of the line, and once in the remaining service life you have quietly shaved off good product. Against that you are trying to catch the subpopulation of units carrying latent defects — weak wire bonds, contaminated epoxy, marginal solder joints, entrapped moisture — that would otherwise fail in the customer's hands during the first weeks or months of operation.
The economics only work if the defect population is genuinely present and genuinely detectable. If your incoming materials, process controls and design margins are sound, burn-in becomes an expensive ritual that mostly weeds out units which would never have failed anyway, whilst aging everything slightly. If your processes are poor, no realistic duration will catch everything and you will ship escapes regardless. Burn-in sits in that awkward middle ground, and optimising it means being honest about which ground you are standing on.
What I see too often is a screen justified once, perhaps fifteen years ago against a specific failure mode that has since been engineered out, carried forward through every process change since. Nobody wants to be the one who removed it. The screen persists, the cost persists, and nobody can say what it is currently catching. That is the situation an economic review needs to break.
What Burn-In Can and Cannot Catch
Burn-in works on failure mechanisms that are both activatable and degrading. Electromigration, contamination-driven dielectric breakdown, die-attach voids that propagate cracks under thermal cycling, intermetallic growth at poorly formed bonds — these have Arrhenius-type or cycle-dependent acceleration behaviour. Apply stress, and the weak units fail on your bench rather than in the field. Apply the same stress to healthy units, and they survive, minus a little life.
It does not work on mechanisms with no meaningful acceleration under your chosen stress. A marginal component that fails only at low temperature will sail through an elevated-temperature soak. A crack that initiates from vibration in service will not be provoked by a thermal screen. Nuisance or wear-out mechanisms sitting far out on the right of the bathtub curve are untouched, which is fine, because you were never going to see them within the warranty period anyway.
The practical test of screen effectiveness is the fallout signature. Plot fallout rate against stress hours. A healthy screen shows a steeply declining hazard: the weak subpopulation is consumed early and the survivors' failure rate flattens. If fallout is flat across the screen duration, you are not screening a defect population — you are sampling from the main distribution, and every additional hour is burning good units as efficiently as bad ones. That single plot tells you more than any debate in a review meeting.
Qualifying a screen before it earns its place
- 01Characterise failuresField returns and line fallout analysed physically: DPA, cross-sections, SEM.
- 02Model accelerationAssign Arrhenius, Coffin-Manson or Black's equation to each mechanism.
- 03Compute the profileEnough acceleration of target defects, bounded wear-out acceleration.
- 04Verify on seeded unitsA screen that cannot catch seeded defects has no evidence of effectiveness.
Life Consumption: The Tax on Good Units
A screen that accelerates the failure mechanisms you care about also accelerates mechanisms you did not intend to touch. Elevated junction temperature drives intermetallic growth in every bond, not just the bad ones. Thermal cycling accumulates low-cycle fatigue in every solder joint. Power cycling flexes every die-attach layer. The acceleration factor you calculated to justify catching the defect is the same acceleration factor applied to the useful life of everything that passes.
For mature, well-characterised products this tax is small and quantifiable: you calculate the fraction of rated life consumed by the screen, document it, and carry on. For products with long service lives and tight reliability budgets — aerospace actuators, medical electronics, safety-critical automotive controllers — every consumed percentage point must be accounted for in the reliability prediction. A screen that consumes a measurable slice of a ten-year design life to catch defects occurring at a rate the field data no longer supports is a net destroyer of value, however comforting the fallout report looks.
I always ask for the life-consumption calculation alongside the fallout data. If the screen owner cannot tell me how much rated life the screen consumes for the intended failure mechanisms and for the dominant wear-out mechanisms, the screen is not under engineering control — it is under institutional inertia. Get both numbers, and the trade-off becomes a discussion about evidence rather than a tug-of-war between caution and cost.
Designing the Screen Around the Physics
A defensible burn-in starts from the failure modes, not from a standard duration. Take your field returns and line fallout, characterise them physically — destructive physical analysis, cross-sections, SEM on fractured surfaces — and identify the mechanisms. For each mechanism, establish or borrow an acceleration model: Arrhenius for temperature-driven chemical and diffusion processes, Coffin-Manson for thermal-cycling fatigue, Black's equation for electromigration, a voltage or current exponent where relevant. Then compute what stress profile delivers sufficient acceleration of the target mechanisms within acceptable acceleration of the wear-out mechanisms.
The stress choice matters as much as the duration. A combined temperature-and-voltage screen can separate mechanisms a simple soak cannot: a unit with oxide defects may fail only when both stresses act together. Screening at cold start-up catches parametric drift and marginal timing that hot soak never will, which is why many automotive module makers run at least one power-on cycle at low temperature rather than relying purely on elevated-temperature soak. Match the stress to the defect's physics, or accept that you are running theatre.
Then verify. Before committing the line to a profile, run a deliberately seeded sample — units built with known marginal characteristics, or a small batch from a process deliberately perturbed within allowed limits — and confirm the screen actually precipitates the defects it was designed to catch. A screen that cannot demonstrate detection on seeded defects has no evidence of effectiveness, only a history of not being questioned.
Monitoring Effectiveness After Release
Once the screen is in production, the work begins. Track fallout rate by week, by line, by component lot and by failure signature. The screen is your best early-warning instrument for incoming material problems: a lot of contaminated die will show up as a fallout spike long before field returns arrive. Correlate screen fallout signatures with physical analysis of a sample of fallen units — you need to know whether you are still catching the designed-in defect population or whether something new has crept in.
A screen that cannot demonstrate detection on seeded defects has no evidence of effectiveness, only a history of not being questioned.
On the other side, track field escapes. Every early-life field failure in a screened product is either a defect your screen cannot activate, a defect whose activation time exceeds the screen duration, or a screen that was not run properly. Until you know which, you cannot tune anything. Build the feedback loop: escape returns get physical failure analysis, the mechanism gets classified, and the screen's coverage of that mechanism gets reassessed. This loop is what turns burn-in from a fixed cost into a managed parameter.
The decision points are explicit. Falling fallout with stable field early-life failure rates invites screen reduction — shorten duration, lower stress, or move to sampling. Rising escapes with stable fallout means the field exposure has shifted and the screen needs strengthening or supplementing with a different stress. Stable fallout dominated by one repeatable mechanism means you should be fixing the upstream process and spending the screen budget on something else. Each of these calls for a different action, and only the data tells you which one you are in.
The Economic Optimisation
The optimisation itself is a comparison of two curves. One is total screening cost: chamber time, energy, floor space, handling, test at temperature, scrap of fallout units and the capitalised value of life consumed on good product, all rising with screen intensity. The other is expected cost of escapes: early-life field failures multiplied through detection, containment, logistics, warranty and reputational weight, falling as intensity rises. Total cost is the sum, and it typically shows a shallow minimum. Your job is to operate near that minimum and re-find it whenever the inputs move.
Uniform screening versus segmented screening
Screen everything uniformly
- Full duration on all units regardless of risk
- Life-consumption tax paid on the whole population
- Chamber capacity throttles end-of-line throughput
- Cost scales with volume, not with defect risk
Screen by segment
- Full screen only on risky builds, suppliers or new processes
- Reduced or sampled profile on the proven remainder
- Life budget spent where risk is demonstrated
- Fallout data defines and re-defines the segments
The inputs move constantly. Field failure costs change with volumes and with how visible failures are to the customer — an escape in a safety-critical application carries a different weight than one in a convenience feature. Upstream process capability changes, altering the size of the defect population the screen exists to catch. Component technology changes, altering acceleration behaviour. Any of these shifts the optimum, which is why I treat screen parameters as living settings with periodic review triggers — fallout signature changes, escape rate changes, major process or supplier changes — rather than as fixed specifications carved at programme launch.
One refinement worth the effort: segment the screen rather than screening everything uniformly. If fallout data shows early-life risk concentrated in a subset — a particular build configuration, a specific supplier's components, a new process introduction — apply the full screen only there and run the remainder on a reduced or sampled profile. Screening smartly beats screening everything, and it preserves the life-consumption budget for the population that genuinely carries elevated risk. Escaping the all-or-nothing framing is usually where the real savings live.
When to Stop Screening
The end state of a good burn-in strategy is its own retirement, at least in full. When the defect mechanisms that justified the screen have been designed out or processed out, when fallout has fallen to the level of the underlying main distribution, and when field early-life failures corroborate that the weak subpopulation is gone, the screen has done its job. Continuing it past that point is pure cost with negative return — you are consuming product life and capital to remove failures that no longer exist.
Retire in steps, with evidence at each step. Reduce duration and watch fallout per hour and field escapes; both should stay flat if the screen was already past the useful region. Move to sampling, then to monitoring. Keep the physical analysis capability and the feedback loop, because those are what let you re-instate a screen quickly and rationally if a new mechanism appears with a supplier change or a process drift.
That is the honest framing of the whole topic. Burn-in is payment for defects you designed in or let through upstream. It can be a rational payment, sized against the physics and the field exposure, or an irrational one, a tax levied out of habit on product that no longer owes it. The difference between the two is nothing more exotic than knowing your failure mechanisms, measuring your fallout and your escapes, and being willing to act on what the numbers say. The capability to screen is an asset; the permanent obligation to screen is a liability.