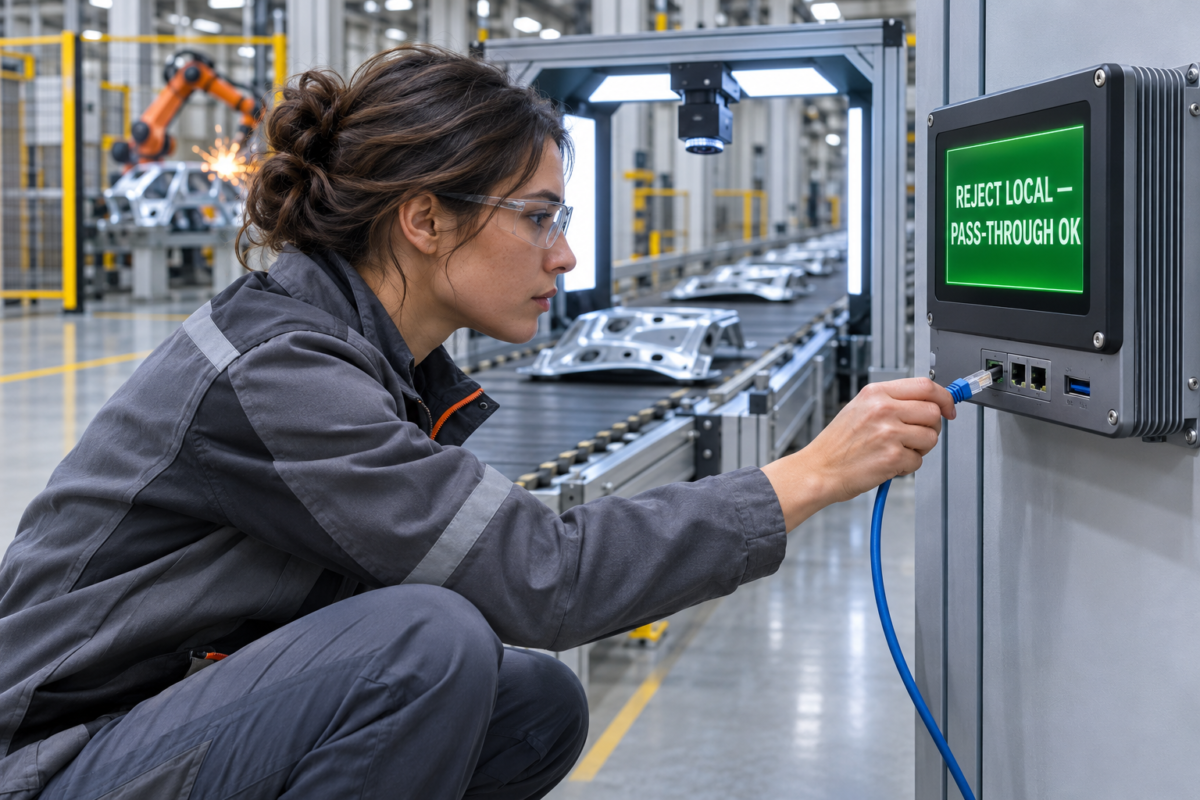
Early in my career I learned a hard lesson about latency on a press line. A vision system flagged a crack, the verdict travelled up to a plant server, then to a cloud dashboard, and by the time anyone acted, several hundred stamped parts had moved downstream. Nobody had designed the system badly; we had simply put the decision in the wrong place. The measurement belonged wherever it was cheap, but the rejection belonged at the line, and we had confused the two.
Edge analytics is fundamentally about that distinction. Not every piece of data needs to travel, and not every decision needs to wait. When a welding controller must decide whether an arc profile is drifting, or a torque station must accept or reject a fastener, the allowable decision window is measured in milliseconds or seconds. Round-trip time to a distant data centre, plus queueing in a message broker, plus whatever the dashboard does with it, does not fit inside that window.
The cloud still matters, but for a different job. Trend detection, fleet-wide comparison, model retraining and traceability reporting tolerate seconds or minutes of delay perfectly well. The engineering task is to sort your decisions by their latency budget, and only then decide where each one executes. Getting that sorting wrong is one of the most common architecture failures in Industry 4.0 projects.
Latency Budgets: Start by Measuring, Not Assuming
Before you architect anything, measure what you actually have. The relevant figure is not bandwidth; it is round-trip time from sensor to decision and back to the actuator, measured under realistic load. I have seen teams quote the ping time to a cloud endpoint from a laptop and build an architecture around it. That number is fiction. Real deployments contend with network congestion, TLS handshake overhead, broker queueing and occasional retries that stretch a nominal 40-millisecond path into multiple seconds.
Break the budget into segments and measure each one: sensor acquisition time, controller scan time, network hop to the edge gateway, inference time on the gateway, network hop to the actuator, and actuator response. Put those numbers on a wall and add them up honestly. Then compare the total against the physical process: how far does the part, the robot or the molten weld pool move during that time? If the part leaves the inspection station before the verdict arrives, you have a sorting problem disguised as a networking problem.
Jitter matters as much as average latency. A loop that responds in 50 milliseconds ninety-nine times out of a hundred and in two seconds on the hundredth is worse, for quality purposes, than one that consistently takes 200 milliseconds. Fasteners get torqued, presses cycle and glue gets dispensed during that outlier. Measure the tail of the distribution, the ninety-ninth percentile and worst case, not the mean, and design your interlocks around the worst case you have actually observed.
Latency figures that decide the architecture
Local Control Loops: What Stays at the Machine
Anything that closes a loop around a physical process belongs in local hardware. Torque-angle monitoring on a nutrunner, weld current and voltage signature checking, in-process gauging that triggers a machine adjustment, presence detection that gates a press stroke: these decisions must execute in the PLC, the weld controller or an industrial PC within arm's reach of the process. The failure mode of sending them elsewhere is not degraded performance; it is lost parts, damaged tooling and, in the worst case, a safety-relevant event.
Design these loops with explicit degradation behaviour. Ask what happens when the edge device loses its uplink, when its inference model file is corrupted, or when the gateway reboots mid-cycle. The correct answer for a local control decision is that the line keeps running on its local logic, alarms locally, and buffers its data for later upload. I insist on testing this deliberately: pull the network cable during a production run and watch what the cell does. If the cell stops or starts passing bad parts, the architecture is wrong, and you have found it cheaply.
Version control on local logic is where discipline often slips. When rejection thresholds live on a dozen smart cameras, each with its own firmware, you can end up with subtly different limits cell to cell and no record of when they changed. Treat edge configuration like any other controlled process parameter: identified, revision-managed, change-noticed and verified after every update. An uncontrolled local decision is a quality escape waiting for its opportunity, however clever the analytics behind it.
Central Visibility: What the Cloud Is Actually For
The plant and enterprise layers earn their keep on aggregation and time. Cycle-by-cycle data from fifty identical stations becomes genuinely useful when you can compare them, watch drift over weeks and detect a fixture wearing faster than its siblings. That comparison needs history and breadth, which is precisely what a local controller cannot provide. The pattern that works is: reject locally, remember centrally, analyse centrally, adjust locally.
Dashboards deserve honest scrutiny. A wall of live gauges that people glance at is visibility as theatre; what you want is a small set of exception views and trend charts tied to specific actions. Who receives the alert when station twelve's weld energy drifts upward for an hour, and what do they do with it? If you cannot answer both questions, delete the view. Every dashboard element without an owner and a response is a cost with no return, and it buries the two signals that genuinely matter.
Central visibility also carries the audit and traceability burden. Serialised records of local accept and reject decisions, with timestamps, parameter snapshots and model versions, are what a customer complaint investigation or a certification audit will demand. Edge devices should publish their verdicts upward as immutable records, and the central store should be the single source of truth for what happened and when. Local buffering during outages is fine, but reconciliation back to central must be automatic and verifiable, or you will discover gaps exactly when you can least afford them.
Splitting the Model: Inference at the Edge, Learning in the Centre
Machine learning complicates the picture, and the split I recommend is inference at the edge, retraining centrally. A vision model classifying surface defects must return its verdict within the cycle time, so it runs on local compute: an industrial PC or an accelerator in the cabinet. But the training corpus, the labelled defect library and the retraining pipeline live centrally, where engineers can curate them and where data from multiple lines improves the model for all of them.
Watch the model deployment path with real care. I have seen a retrained model shipped to the edge silently change its false-reject behaviour, flooding a scrap bin overnight because a new lighting condition confused it. The defensible sequence is staged rollouts, shadow mode where the new model runs alongside the old one and its verdicts are logged but not acted upon, and a documented rollback. Model drift monitoring belongs in the central layer: compare the live distribution of input images or features against the training distribution, and alarm when they diverge.
Reject locally, remember centrally, analyse centrally, adjust locally — every other pattern eventually costs you parts or traceability.
There is also a data-volume argument that people underestimate. A line-scan camera generating full-resolution frames produces an enormous stream, and shipping all of it centrally is expensive and fragile. Filter at the edge: send the verdicts and metadata always; send the images only on rejects, on borderline scores or on a sampled basis. That policy preserves traceability and the training pipeline while keeping the network load sane. Decide the sampling rules deliberately, in writing, rather than letting whoever set up the MQTT topics decide them by accident.
Failure Modes Worth Designing Against
Latency failures announce themselves quietly. A cell that passes everything because the inspection verdict consistently arrives after the mechanical gate has already actuated. A historian whose timestamps are set at the server rather than the sensor, so your sequence-of-events reconstruction after a quality escape is worthless. A fail-open interlock that treats a crashed analytics process as an absence of defects. I have seen each of these; each produced scrap or escapes that took weeks to diagnose.
Time synchronisation is the quiet foundation of the whole structure. Every edge device, PLC and gateway should sit on a disciplined network time source, because without it you cannot correlate the weld signature with the part serial, the alarm with the operator action, or the model output with the machine state. Check it during commissioning and periodically afterwards; clock drift on an air-gapped camera is a classic. Timestamp at the point of measurement, not at the point of storage, and carry the measurement timestamp through the whole pipeline.
Security failures at the edge have quality consequences. A smart camera on default credentials is not merely an IT problem; it is a device making accept and reject decisions that someone else may control or disable. Patch management on edge devices needs the same rigour as the production software on your PLCs: a defined window, a rollback and a functional verification after every update. A vision system that sees differently after a firmware patch is a measurement system that needs revalidation.
A Practical Way to Decide
When I run this exercise with a team, we take every automated decision on the line and ask three questions in order. What is the consequence window, the time before a wrong decision becomes irreversible damage or an escaped defect? What is the worst-case round trip to wherever we were thinking of executing it? And what must happen if that path is unavailable? The answers sort decisions naturally into three bins: hard real-time, soft real-time and deferred. Only the last bin belongs in the cloud.
The three-question sort for every automated decision
- 01Consequence windowHow long before a wrong decision becomes damage or an escape?
- 02Worst-case round tripMeasured under load, at the tail of the distribution, not quoted from a laptop.
- 03Degradation behaviourWhat the station does when the execution path is unavailable.
- 04Assign the binHard real-time, soft real-time or deferred; only deferred goes to the cloud.
Then write the architecture down as a simple decision register: each decision, its latency budget, its execution location, its degradation behaviour, its owner and its verification method. That register becomes the document your controls engineer, your IT function and your quality team all sign, and it is the first thing you review when someone proposes moving a decision. Architecture arguments end quickly when the consequence window for a torque decision is written in black ink next to the proposal to analyse it in a distant data centre.
Finally, test the boundaries on the floor, not in the meeting room. Pull cables, kill gateways, saturate the network during a trial run, and record what actually happens at each station. Edge analytics succeeds not because the diagrams are elegant but because every decision executes where its physical consequences live, and because someone has deliberately, repeatably verified that it still does when things go wrong.