Every warranty report is a biased sample of reality. The failures listed are the units that broke. The far larger population — units still running, units sold late in the period, units quietly accumulating mileage in customers' hands — contributes nothing to the failure count. Divide claims by production volume and you underestimate the failure rate, worst for the newest builds, which is precisely where design weaknesses first appear.
The defining feature of warranty data is censoring. A unit that has not failed has not told you it will survive forever; it has told you it survived to its current age or mileage. Discarding those units throws away most of your information. Treating them as failures inflates the estimate in the opposite direction. Survival analysis uses both kinds of observation correctly, and it is the most underused statistical tool in quality departments outside dedicated reliability groups.
This article sets out the structure of real warranty records, the two functions that carry the analysis, a non-parametric baseline, parametric projection into the unobserved tail, and the complications — repeat claims, competing risks, mileage — that decide whether the numbers can be trusted.
Right Censoring and Left Truncation in Real Warranty Records
Right censoring is the bread-and-butter case. A gearbox shipped in March and still operating in December has a survival time of at least nine months — a lower bound, nothing more. Across a fleet, the majority of recent production months are censored. A naive calculation restricted to failed units alone asks: of the units that failed, how long did they last? That question conditions on the very event you are trying to predict and has almost no operational meaning.
Left truncation is the quieter trap. A unit only enters your data once it is sold and registered; exposure to risk does not begin at the factory gate. Measure age from production date when the customer took delivery three months later, and you have credited the unit with risk time during which failure was impossible. Mileage accumulation compounds it: a delivery van and a weekend car with the same build date have wildly different usage intensities.
Good warranty analyses therefore work with time in service adjusted for delivery lag, or with mileage where telematics or inspection data allow it. Before fitting anything, plot the number of units at risk by age for each production cohort. If a cohort was sold six months ago, its hazard curve beyond six months is pure extrapolation — say so in the report. A Weibull tail estimated from three failures, presented as established fact, has burned more than one quality manager in front of a customer.
The Survival Function and the Hazard Rate
Two functions carry the analysis. The survival function S(t) gives the probability a unit still functions at age t; it starts at one and declines. The hazard rate h(t) is the instantaneous failure intensity among units still alive at t. The hazard is where the engineering lives: a hazard rising steadily with age points to wear-out — bearing fatigue, bushing degradation, corrosion — while a hazard high early and falling points to manufacturing or assembly defects killing weak units quickly, the classic infant mortality pattern.
The Weibull distribution remains the workhorse because its hazard can take either shape. Shape parameter below one gives decreasing hazard, above one increasing, near one roughly constant. But do not force Weibull onto everything. Coolant pumps with an early defect batch plus later shaft wear produce a bathtub-shaped hazard a single Weibull cannot represent; a two-population mixture or piecewise approach fits better and, more importantly, tells the correct engineering story.
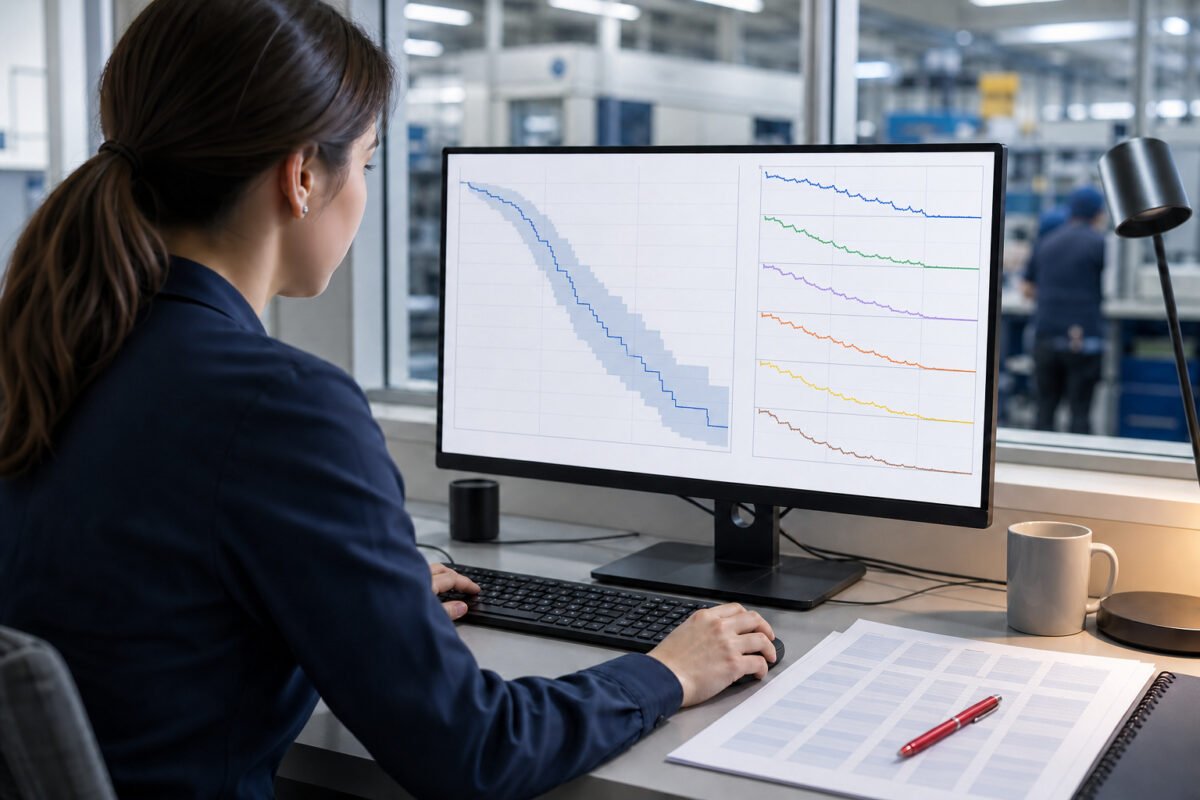
When I review someone else's analysis, the first thing I look at is the confidence band, not the point estimate. With many censored units and few failures, the Kaplan-Meier curve is honest but wide, and that width is information. A narrow claim about a failure rate from thin data means somebody assumed a distribution rather than estimated one — and you need to know which assumption, and why.
Kaplan-Meier as the Non-Parametric Baseline
Start every warranty analysis with Kaplan-Meier, before any distributional assumptions. The estimator works from a life table: at each distinct failure age, divide the number of units failing by the number at risk — units that reached that age without prior failure, whether or not they later fail. Multiply the successive survival proportions and you get a step-function curve that correctly accounts for censoring. No distribution assumed, no shape imposed.
Building that life table demands discipline in the data. For every serialised unit you need production date, sale or registration date, current status (failed, in service, scrapped, lost from observation), failure date or usage if failed, and claim mode for stratified curves. Units lost from observation — exported, written off in accidents, retired early — are censored at their last known good age.
Accidental loss of a functioning unit is not the same as removal of a fragile one. If customers scrap vehicles because of an intermittent fault you could not replicate, the censoring becomes informative and the curve drifts optimistic. Interrogate that possibility every time. Then stratify: split by plant, by supplier batch, by build month, and plot the curves on one chart. A separation visible before any formal test often identifies the problematic population in an afternoon, and gives you a defensible picture for the supplier discussion.
From raw warranty records to a defensible curve
- 01Reconstruct unit historiesProduction date, sale date, status, failure date per serial number
- 02Assign censoring agesAt-risk time ends at failure or last known good observation
- 03Check truncation and lagAge from service start, not factory gate
- 04Fit Kaplan-MeierStep-function survival curve, no distribution assumed
- 05Stratify and compareSplit by plant, batch, build month to isolate populations
Fitting Distributions and Projecting the Tail
Non-parametric curves stop at the oldest observed failure. Warranty management needs to see further: the claim rate at three years or 100,000 kilometres when most of the fleet is younger. Parametric survival regression — Weibull, log-normal, log-logistic, occasionally gamma — extrapolates the hazard beyond observed ages, and covariates separate the effect of a running change from underlying aging. A Weibull model with a covariate for a revised valve seat material, fitted to mixed data before and after the change, tells you whether the change shifted the scale parameter enough to matter.
Maximum likelihood handles censoring natively: each censored unit contributes its survival probability to the likelihood rather than a failure time. Any competent survival package does this, but the analyst must supply the correct censoring indicator. I have seen more than one analysis wrecked by a mis-coded status field where claims were marked zero and in-service units one. Check the at-risk counts the software reports against your own tally before trusting a single parameter.
Extrapolation deserves humility. Beyond the last failure, the model is in charge, not the data. A Weibull tail with shape well above one projects steeply rising costs at ages you have never observed; if the true failure mode is capped by design life or by a subset of susceptible units, you will over-reserve badly. Present projections with the confidence band, state the age beyond which the fit is unsupported, and give a sensitivity view using two candidate distributions. When Weibull and log-normal disagree materially at the ages that matter, that disagreement is the finding.
Beyond the last observed failure, the model is in charge, not the data — and the report must say so.
Recurring Claims, Competing Risks and the Mileage Dimension
Real warranty data refuses to stay tidy. Some units fail more than once — a seal replaced under claim fails again — and Kaplan-Meier assumes one event per unit. Recurrent-event methods, or simpler gap-time analyses treating each repair-to-repair interval separately, keep repeat offenders from being double-counted or wrongly ignored.
Competing failure modes need attention too. If you are projecting the hazard for the EGR valve, a claim coded for a neighbouring component on the same visit contaminates your extraction unless the claim taxonomy is clean. I have spent more hours reconciling labour-operation codes to true component failures than I care to admit; the analysis is only ever as good as that mapping.
Mileage adds a second time scale. Units accumulate distance at different rates, and failure depends on both calendar age and usage. Either analyse mileage with mileage-censored data — an odometer reading at last observation is a lower bound — or model usage rate explicitly and convert. Ignore mileage in a population mixing commercial and private fleets and you will conclude the commercial units are unreliable when they simply live harder. A usage-rate adjustment, even a crude segmentation, usually explains most of the apparent gap.
Turning the Curves into Decisions
The output that matters to the business is a projection of future claims by age and cohort: how many failures to expect from units already in the field, at what cost, over what horizon. Build it by applying the fitted survival function to the current fleet profile — units at each age, censored, still at risk — and accumulating expected failures period by period. Field-action decisions, reserve setting and the timing of a running change all hang off this number, so the uncertainty band belongs in the decision paper, not in an appendix.
The hazard shape steers the response. Falling hazard concentrated in the first months points to escape control and supplier process issues; the countermeasure is containment and improved outgoing checks, not redesign. Rising hazard at later ages points to genuine durability shortfall; the countermeasure is a design or material change, and the survival model tells you how much of the fleet has not yet reached the risky window — hence how much is still saveable.
Reading the hazard shape before choosing a countermeasure
Early, falling hazard
- Manufacturing or assembly defects
- Infant mortality of weak units
- Containment and escape control
- Improve outgoing checks and supplier process
Late, rising hazard
- Wear-out: fatigue, corrosion, degradation
- Genuine durability shortfall
- Design or material change
- Quantify fleet not yet in the risk window
Survival analysis is not a statistical exercise for its own sake. It is how you read an incomplete fleet honestly, reserve correctly, and act before the tail arrives. Quality departments that treat censored units as information rather than noise will see design weaknesses months earlier than those counting claims against volume — and will not be surprised by the newest builds.
The practical starting point costs little: reconstruct unit histories, apply Kaplan-Meier, stratify by cohort, and look at where the curves separate. Everything beyond that — parametric fits, covariates, mileage models — earns its complexity only when the baseline curve has already told you where the problem lives.