Large language models have changed how quality professionals draft documents. A procedure that once took a full morning to structure can now be drafted in an hour and reviewed in a second. The blank-page problem, which stalls most of us, is gone: ask for a supplier corrective action request in a defined format and a coherent skeleton appears in seconds. That gain is real, and pretending otherwise helps nobody.
But these tools excel at transformation work, not creation work. Converting a badly structured audit report into a clean findings register, reformatting a complaint log into a Pareto-ready summary, compressing fifty pages of process documentation into a management briefing — these are tasks with verifiable output. The input is known, the transformation is mechanical, and errors are easy to spot. That is exactly why the tool can be trusted there, and nowhere else without checking.
The trap is treating fluency as competence. The output reads as though it was written by someone who knows your business. It was not. It was written by a statistical system predicting plausible text. The draft is where the work starts, not where it ends, and every rule in this article follows from that one distinction.
Where These Tools Genuinely Earn Their Place
Drafting audit checklists is an honest use, provided you feed the tool real material. Give it your process descriptions, your last audit findings and your risk register, then ask for proposed questions per process owner. It produces sensible, sometimes sharp, lines of enquiry you had not considered. The correct mental model is a tireless junior auditor with a good memory of general practice and no memory of your plant.
Audit preparation is where adoption is highest, and reasonably so. Before a third-party audit there is always a scramble to brief process owners, refresh evidence locations and rehearse the difficult questions. An LLM will run a mock interview with your production manager, playing the auditor role with uncomfortable realism. People who freeze in real audits loosen up when the auditor is a browser tab.
Nonconformity wording is another legitimate application. Auditors and quality managers alike struggle to write findings that are specific, evidence-based and traceable to a requirement. Give the model the raw observation and the clause reference and it drafts three variants of the finding statement. Choose one, edit it, and verify the citation against the standard text itself — not against the model's memory of the standard.
The LLM work cycle in a controlled system
- 01Prepare inputsReal process documents, findings and risk register — never vague prompts.
- 02Generate draftChecklists, matrices, finding wording, summaries.
- 03Verify against sourceClause citations, revisions, numbers and completeness checked by a person.
- 04Process owner reviewAdequacy for the actual process judged by someone who knows it.
- 05Approve and controlNamed author and approver; prompts and outputs retained if consequential.
Audit Preparation Without the Panic
Evidence mapping is the highest-value audit application. Paste in your process landscape and ask the tool to tabulate which objective, indicator, procedure and record supports each clause requirement. It produces in minutes a matrix that would take a day to build manually. Then — and this is the whole point — you walk that matrix against your actual document management system and correct it, because it will have invented document numbers, conflated revision levels or cited procedures you retired two years ago.
What must be forbidden is generating retrospective evidence or filling gaps in preparation. If the tool writes a training record summary for a session that ran but was poorly documented, that is a recording task with a defensible basis. If it writes one for a session that never happened, that is fraud, and no sophistication of the tool changes the character of the act. The line is not blurry. People who claim it is blurry have already crossed it.
The practical safeguard is a short internal standard that says what may be drafted with LLM assistance, what may never be, who approves, and what gets checked. Written in plain language and trained to the affected roles before use, not after the first audit finding, it closes the loop between tool capability and organisational rules.
The Verification Duty Stays With You
The model has no verification duty, because it has no duty at all. Duties belong to people, and in a certified management system the duty to ensure records are accurate and fit for purpose belongs to named roles. Delegating drafting to software delegates nothing else. If a document goes out under your name or your department's name, the accuracy of every sentence in it is yours.
Practical verification means checking three distinct things. Internal consistency: does the document contradict itself, cite the wrong revision, or reference a process step that no longer exists? Models drift in long documents, contradicting in section four what they wrote in section two. External accuracy: every standard reference, regulatory citation, customer-specific requirement and technical parameter is checked against source. Adequacy: is the content right for your context, equipment and risk level? Only a person who knows the process can judge the third.
A review signature with no real review is an old failure mode that these tools make easier to commit.
Citations fail in a specific, dangerous way. A model asked about product traceability requirements will produce something that looks like a quotation — clause number, structure, formal language — and it may be a paraphrase, a blend of two standards, or entirely invented. Fabricated clause references survive into audit preparation packs. The fix is mechanical: no standard reference enters a document unless someone has read it in the source text and recorded the revision of that source.
Traceability of the drafting itself is worth deciding on as an organisation. Some companies log which documents had LLM assistance; others do not, on the grounds that the reviewed output is the only relevant artefact. Either policy works, provided the review record is genuine. If document control says the quality manager reviewed the draft, then the quality manager reviewed it — meaningfully, with edits, not a rubber stamp on machine text.
Confident Errors and Where They Bite
The failure mode has a name: hallucination. The model generates text that satisfies the pattern of a correct answer with no mechanism for checking whether it is true. I have seen an LLM state with perfect fluency that an aluminium alloy temper suits a fatigue-critical application when the source it was implicitly drawing on described a different product form. A metallurgist catches it in seconds. A junior engineer under deadline pressure might not.
Numbers are the sharpest risk. Ask a model to compute a tolerance stack or convert a measurement result and it may produce arithmetic that looks right and is not, or unit conversions that mix metric and imperial without flagging it. The rule I enforce is simple: any quantity, tolerance, torque value, temperature limit or measurement uncertainty that originated from model output is recalculated by a person or by validated software before it touches a controlled document.
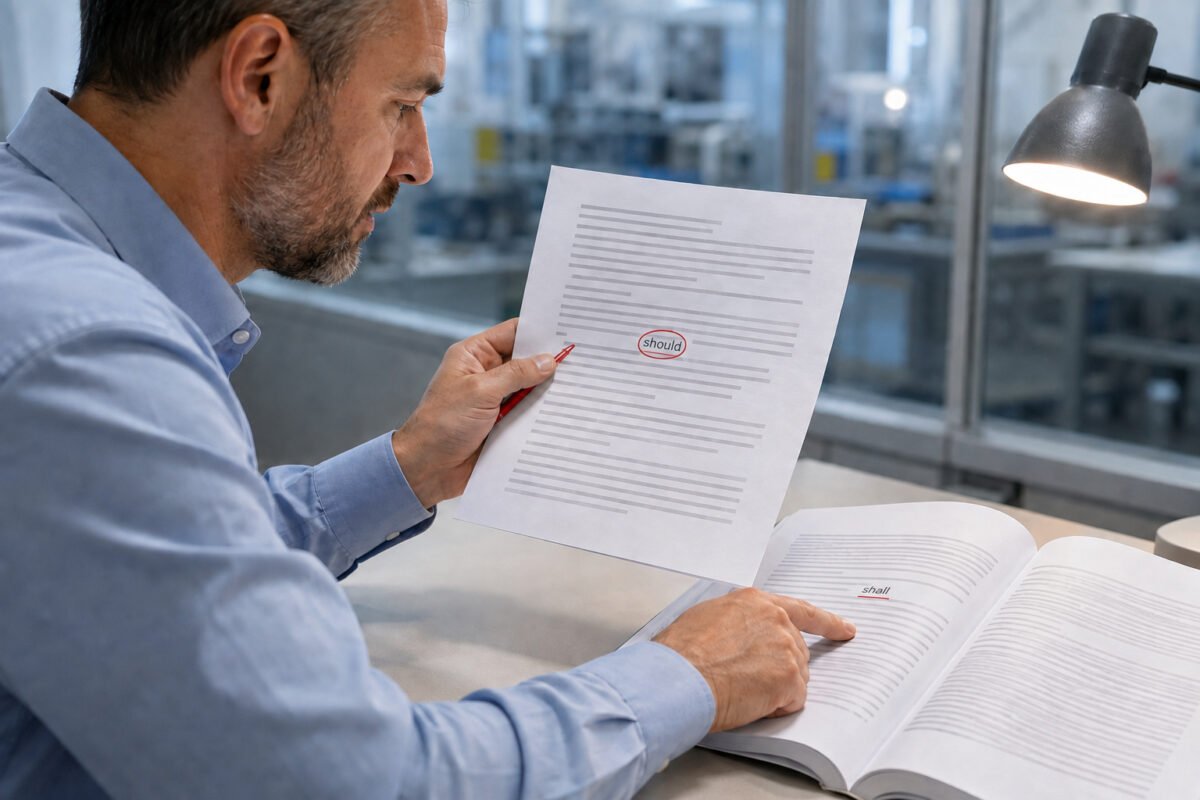
Tone drift in normative text is quieter but just as costly. Models trained largely on agreeable, helpful prose soften obligations: "the operator shall verify" becomes "the operator should verify". In an audit, that single word change is a finding, because shall and should carry different weight in normative language. Every modal verb in an LLM-assisted procedure gets read aloud in review. It sounds pedantic; it is not.
What fails and how to catch it
The failure mode
- Fabricated clause citations that look like quotations
- Arithmetic and unit errors that look plausible
- Modal verbs softened from shall to should
- Missing hold points, cleaning steps, notification requirements
The control
- Read every reference in the source text; record its revision
- Recalculate every quantity before controlled use
- Read modal verbs aloud in procedure review
- Process owner review, not quality function alone
The most insidious failure is completeness. The draft reads so well that nobody asks what is missing. A rework instruction may omit a cleaning step, a hold point or a customer notification requirement — not by choice, but because the pattern of similar documents it learned from contained none. Omissions leave no trace in the text. Only someone who knows what must be there can catch them, which is why LLM-drafted procedures are reviewed by the process owner, not just by the quality function.
Making It Traceable in a Controlled System
Document control implications are real and under-discussed. Your management system assumes documents have identifiable authors and approvers. Machine-drafted documents fit this fine — the author is the person who prompted and edited, the approver is whoever signs — but only if you decide that consciously and state it in your document control procedure. Silence in the procedure means ambiguity in the audit.
For records, the standard is stricter. A record is evidence that something happened. Model-generated summaries of records are convenient but they are not records; they are derived views, and derived views can misrepresent. If you use an LLM to summarise nonconformance reports for a management review, the summary must be labelled as derived, and the source reports must remain the evidence. Spot-check the categorisation against the raw data — sampling ten reports and confirming they landed in the right category keeps the summary honest.
Retention and reproducibility matter more than people expect. If a tool's output informed a consequential decision — an audit-readiness risk assessment, say — and that decision is later questioned, you must be able to state what the tool was given and what it produced. Keep prompts and outputs with the project file. This is not bureaucratic overreach; it is the same logic as retaining calibration records. You are evidencing the basis of a decision.
Accountability Cannot Be Automated
The accountability question is simple: when a machine-drafted document causes a bad decision, who answers for it? Under customer-specific requirements, product safety regulations and the general duty of a manufacturer, the answer is the organisation and the named individuals within it. No regulator accepts "the software wrote it" as an explanation, and none ever will, because accountability that can be delegated to a tool is not accountability at all.
So the practical position, after two years of daily use, is this. Use the tools for drafts, transformations, rehearsals and first-pass analysis; they are genuinely better than nothing and often better than we are. Then apply human verification with the same rigour you apply to any other outsourced process — because that is exactly what this is. An LLM is a supplier of draft text: capable, fast, never to be trusted on its own assertion, and always subject to incoming inspection.
The quality professional's role shifts rather than shrinks. Less time drafting; more time verifying, judging adequacy and owning the consequences. That is not a diminished role. It is the role, made visible — and the organisations that understand this earliest will extract the value without paying for it in audit findings.